Introduction 


LaminDB is an open-source data management tool that makes it easy to query, trace and govern datasets across diverse storage formats and locations. Like git, LaminDB is a distributed system that runs anywhere and captures all relevant context about your work. This includes the data flow through models and analyses, the entities and notes defining your work, and the features & schemas of datasets. It takes a few seconds to install LaminDB and create a database on your laptop.
Why?
Untraceable results cannot be trusted, especially when non-verifiable tasks are delegated to agents.
Without effective access to multimodal data, models burn tokens or fail entirely.
Without governing changes to data akin to governing changes to software with git, it’s hard to evaluate agents, debug their mistakes, and safely merge their contributions.
Especially in life sciences, hard-to-verify tasks are abundant, data formats are very heterogeneous, and teams need end-to-end traceability for GxP compliance (21 CFR Part 11 and EU Annex 11).
Traditional data infrastructure doesn’t solve these issues because it was built for business analytics rather than complex AI workflows.
While modern SQL lakehouse solutions (Iceberg, Delta, DuckLake, Lakebase) excel at tabular analytics, they are restricted to structured rows and SQL-centric catalogs.
LaminDB generalizes core lakehouse guarantees — ACID transactions, time travel, and schema evolution — to multimodal data (parquet, zarr, AnnData, …) and Python-first workflows, giving you lakehouse governance over non-tabular data while letting you query and load with your favorite engines (Polars, DuckDB, annbatch, …).

How?
lineage → trace results across agent sessions, notebooks, scripts & workflows
lakehouse → manage datasets in any format (
parquet,zarr, …) with time travel, schema evolution & ACID guarantees; load/query with your favorite engine (Polars, DuckDB,annbatch, …)LIMS & ELN → unified schema-based records management with support for ontologies & notes
FAIR datasets → validate & annotate files,
DataFrame,AnnData,SpatialData, …governance → manage changes via branching & versioning
Architecture?
zero lock-in → open source, using open standards (metadata in SQLite/Postgres, data in
parquet,zarr, etc.)scalable → hit storage & database directly through your
pydataor R stack, no REST API involvedsimple →
pip install lamindborinstall.packages('laminr')· no Docker required, no separate backendunified access → local, S3, GCP, etc. · Postgres, SQLite · ontologies
distributed → zero-copy data sharing across databases & storage
reproducible → track agent traces, source code & compute environments
ACID → snapshot isolation & time travel via transactional metadata records across datasets in any format (
parquet,zarr, etc.)idempotent → re-run logic without worries about duplications or overwrites
decoupled compute → run your favorite engine (Polars, DuckDB, data loaders, …) with all its benefits
integrations → bio ontologies, git, nextflow, vitessce, redun, and more
extensible → create custom plug-ins based on the Django ORM, the basis for LaminDB’s registries
Read more: docs.lamin.ai/architecture.
Who?
Scientists and engineers at leading research institutions and biotech companies, including:
Industry → Pfizer, Altos Labs, RefinedScience, Ensocell Therapeutics, …
Academia & Research → scverse, DZNE (National Research Center for Neuro-Degenerative Diseases), Helmholtz Munich (National Research Center for Environmental Health), …
Research Hospitals → Global Immunological Swarm Learning Network: Harvard, MIT, Stanford, ETH Zürich, Charité, U Bonn, Mount Sinai, …
From personal research projects to pharma-scale deployments managing petabytes of data across:
entities |
OOMs |
|---|---|
observations & datasets |
10¹² & 10⁶ |
runs & transforms |
10⁹ & 10⁵ |
proteins & genes |
10⁹ & 10⁶ |
biosamples & species |
10⁵ & 10² |
… |
… |
UI, permissions, audit logs?
Lamin is a collaboration hub built on LaminDB similar to how GitHub is built on git.
Platform features:
permissions → role-based, fine-grained access management for humans, bots & teams
audit logs → full traceability for compliance
single sign-on → social logins, Okta, Ping, and other providers
secure → SOC2 certified, monitoring ISO27001 & HIPAA compliance
infra-as-code → manage many databases and storage locations
Architecture features:
zero lock-in → LaminDB ensures data remains yours & accessible even if you cancel Lamin
permissions on the Postgres & storage layer → no need for an intermediate web service
TRE (Trusted Research Environment) → manage sensitive data from e.g. the UK Biobank
auto-generated REST API → optional REST interface for JavaScript-based web applications
UI features:
lineage → interactive graphs for records, datasets, notebooks & pipelines
catalog → browse, search & query records and datasets
notebooks, workflows, runs → visualize & launch executions
versioning → manage data & code revisions
LIMS & ELN → records & notes integrated with ontologies
schemas, features, labels → manage data models
simple dashboarding → auto-generate data summaries
Give it a try by exploring public databases at lamin.ai/explore. It’s free and no account is required.
For private data & commercial usage, see: lamin.ai/pricing.
Quickstart
To install the Python package with recommended dependencies, use:
pip install lamindb
Install with minimal dependencies.
The lamindb package adds data-science related dependencies through the [full] extra, see here.
For a minimal install of the lamindb namespace, use:
pip install lamindb-core
Agent? See .agents/, docs/ and llms.txt.
Query databases
You can browse public databases at lamin.ai/explore. To access laminlabs/cellxgene, run:
import lamindb as ln

db = ln.DB("laminlabs/cellxgene")  # a database object for queries
df = db.Artifact.to_dataframe()    # a dataframe listing datasets & models
library(laminr)
ln <- import_module("lamindb")

db <- ln$DB("laminlabs/cellxgene")  # a database object for queries
df <- db$Artifact$to_dataframe()    # a dataframe listing datasets & models
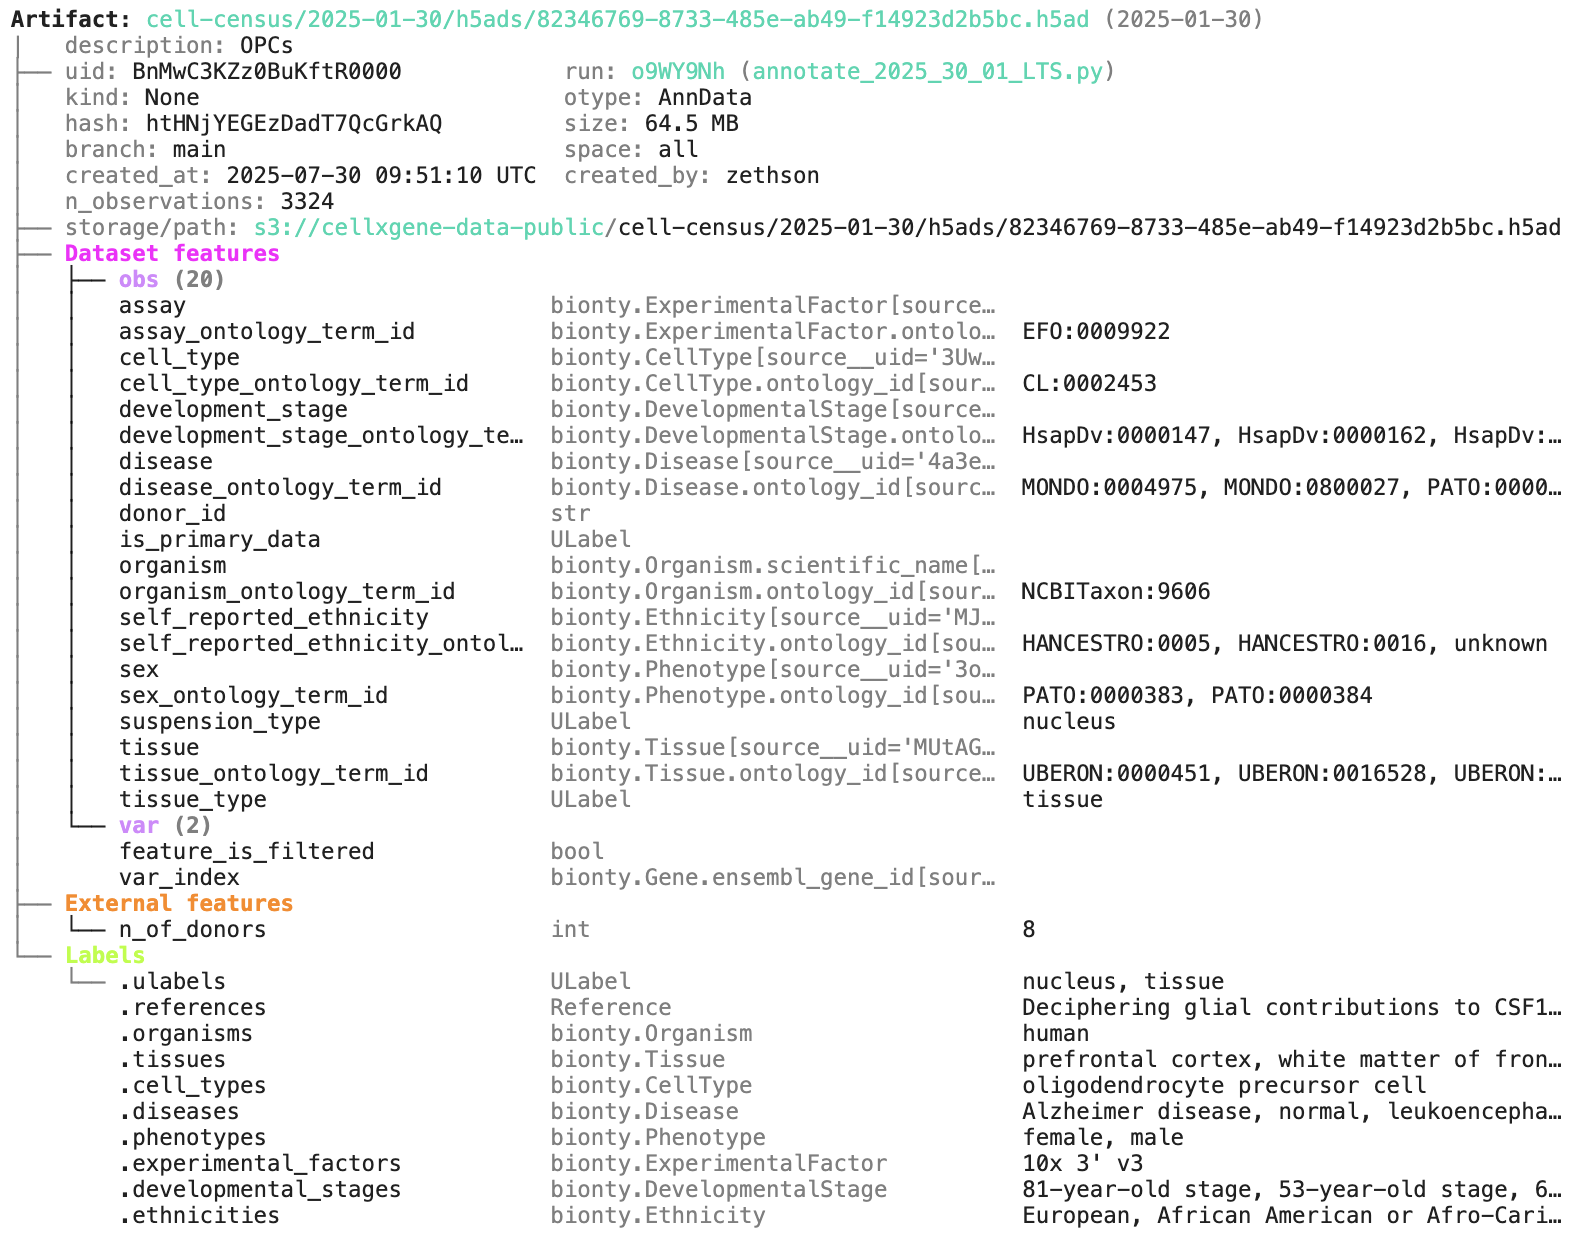
To get a specific dataset, run:
artifact = db.Artifact.get("BnMwC3KZz0BuKftR")  # a metadata object for a dataset
artifact.describe()                             # describe the context of the dataset
artifact <- db$Artifact$get("BnMwC3KZz0BuKftR")  # a metadata object for a dataset
artifact$describe()                             # describe the context of the dataset
See the output.
Access the content of the dataset via:
local_path = artifact.cache()  # return a local path from a cache
adata = artifact.load()        # load object into memory
accessor = artifact.open()     # return a streaming accessor
local_path <- artifact$cache()  # return a local path from a cache
adata <- artifact$load()        # load object into memory
accessor <- artifact$open()     # return a streaming accessor
For broader queries of cellxgene, see docs.lamin.ai/cellxgene.
Create artifacts
You can create a hosted database at lamin.ai and invite collaborators. To connect to an existing database, run:
lamin login
lamin connect account/name  # tip: add flag `--here` to scope to current directory
Or init a new database instead (no login required).
Navigate into a development directory, just like you’d do for git init, and run:
lamin init --modules bionty
For more configuration, see docs.lamin.ai/setup.
On the terminal and in a Python session, lamindb will now auto-connect.
To save a file or folder via the API:
import lamindb as ln
# → connected lamindb: account/instance

open("sample.fasta", "w").write(">seq1\nACGT\n")        # create dataset
ln.Artifact("sample.fasta", key="sample.fasta").save()  # save dataset
library(laminr)
ln <- import_module("lamindb")
# → connected lamindb: account/instance

writeLines(">seq1\nACGT\n", "sample.fasta")        # create dataset
ln$Artifact("sample.fasta", key = "sample.fasta")$save()  # save dataset
To save a file or folder via the CLI, run:
lamin save sample.fasta --key sample.fasta
To load an artifact via the CLI into a local cache, run:
lamin load --key sample.fasta
Read more about the CLI: docs.lamin.ai/cli.
Trace data, code & agents
To track agent sessions, install the library skill: uvx library-skills --skill lamindb.
To track source code, inputs, outputs, logs, and environment of a script, use ln.track() and ln.finish():
import lamindb as ln
# → connected lamindb: account/instance

ln.track()                                              # track code execution
open("sample.fasta", "w").write(">seq1\nACGT\n")        # create dataset
ln.Artifact("sample.fasta", key="sample.fasta").save()  # save dataset
ln.finish()                                             # mark run as finished
library(laminr)
ln <- import_module("lamindb")
# → connected lamindb: account/instance

ln$track()                                              # track code execution
writeLines(">seq1\nACGT\n", "sample.fasta")        # create dataset
ln$Artifact("sample.fasta", key = "sample.fasta")$save()  # save dataset
ln$finish()                                             # mark run as finished
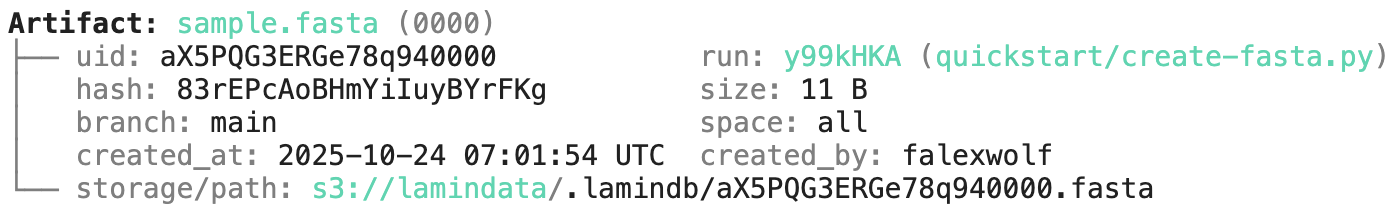
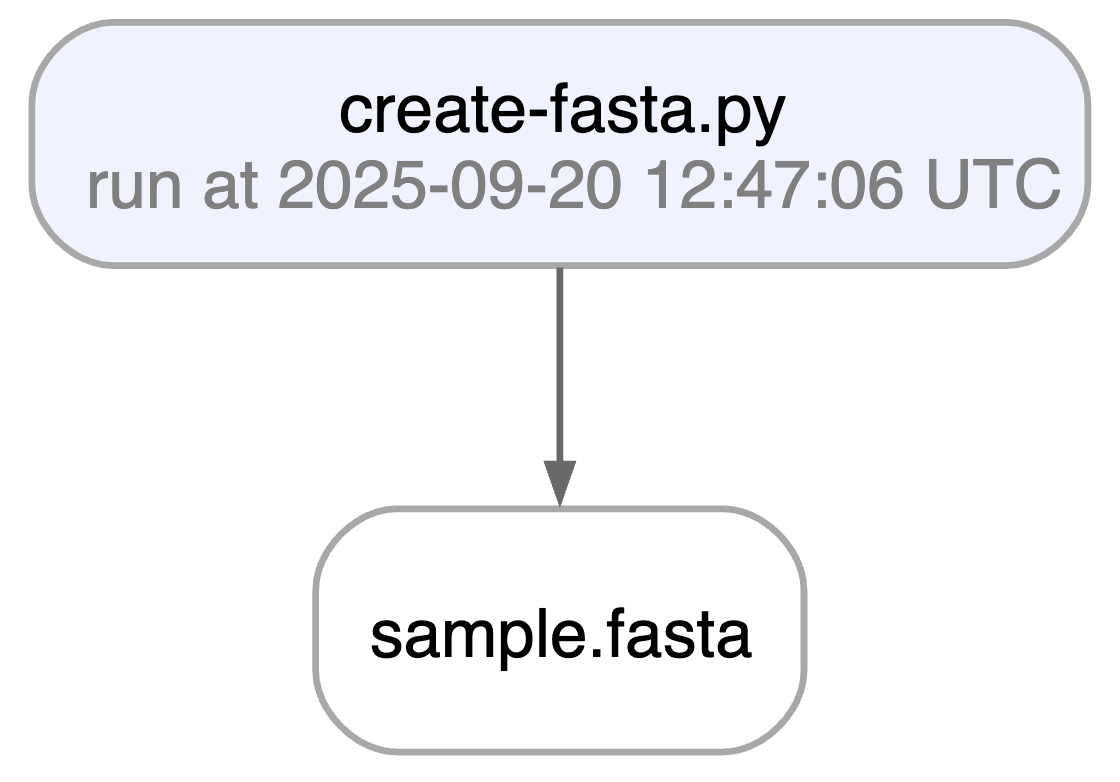
If running this snippet as a script (python create_fasta.py), you’ll get the following data lineage:
artifact = ln.Artifact.get(key="sample.fasta")  # get artifact by key
artifact.describe()      # context of the artifact
artifact.view_lineage()  # fine-grained lineage
artifact <- ln$Artifact$get(key = "sample.fasta")  # get artifact by key
artifact$describe()      # context of the artifact
artifact$view_lineage()  # fine-grained lineage
Watch a mini video: youtu.be/yK3ODFZLL1A
Access run & transform.
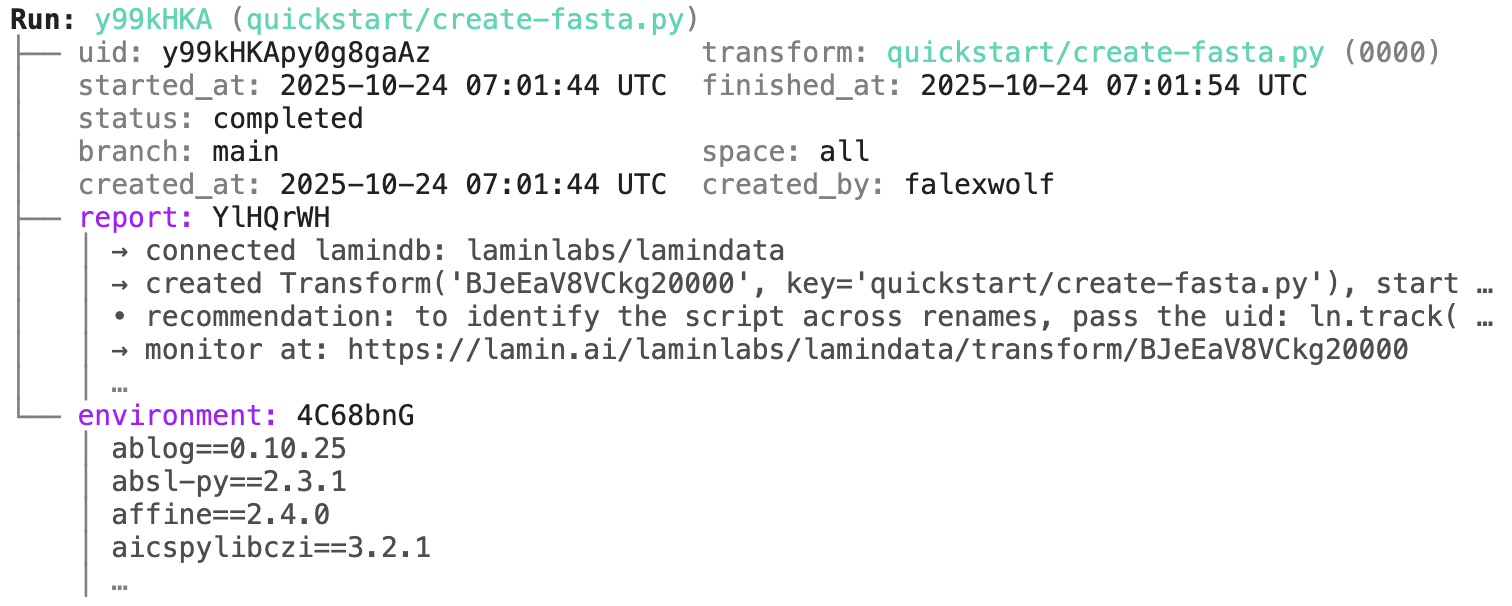
run = artifact.run                     # get the run object
transform = artifact.run.transform     # get the transform object
run.describe()                  # context of the run
run <- artifact$run                     # get the run object
transform <- artifact$run$transform     # get the transform object
run$describe()                  # context of the run
transform.describe() # context of the transform
transform$describe() # context of the transform
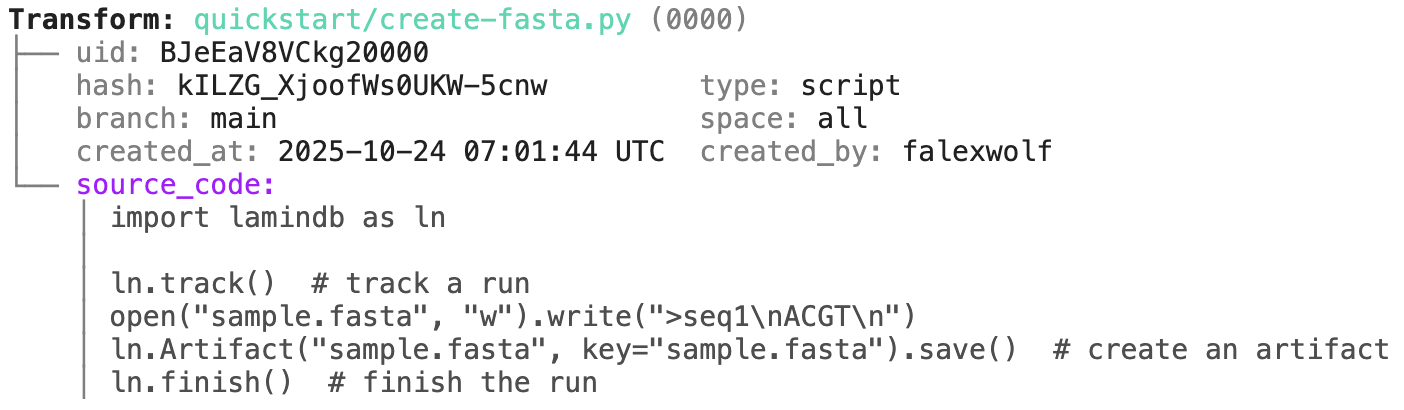
Track a project or an agent plan.
Pass a project/artifact to ln.track(), for example:
ln.track(project="My project", plan="./plans/curate-dataset-x.md")
ln$track(project = "My project", plan = "./plans/curate-dataset-x.md")
Note that you have to create a project or save the agent plan in case they don’t yet exist:
# create a project with the CLI
lamin create project "My project"

# save an agent plan with the CLI
lamin save /path/to/.cursor/plans/curate-dataset-x.plan.md
lamin save /path/to/.claude/plans/curate-dataset-x.md
Or in Python:
ln.Project(name="My project").save() # create a project in Python
ln$Project(name = "My project")$save() # create a project in Python
You can track workflows by decorating functions:
import lamindb as ln

@ln.flow()
def create_fasta(fasta_file: str = "sample.fasta"):
    open(fasta_file, "w").write(">seq1\nACGT\n")    # create dataset
    ln.Artifact(fasta_file, key=fasta_file).save()  # save dataset

if __name__ == "__main__":
    create_fasta()
Beyond what you get for scripts & notebooks, this automatically tracks function & CLI params and integrates well with established Python workflow managers: docs.lamin.ai/track. To integrate advanced bioinformatics pipeline managers like Nextflow, see docs.lamin.ai/pipelines.
A richer example.
Here is an automatically generated re-construction of the project of Schmidt et al. (Science, 2022):
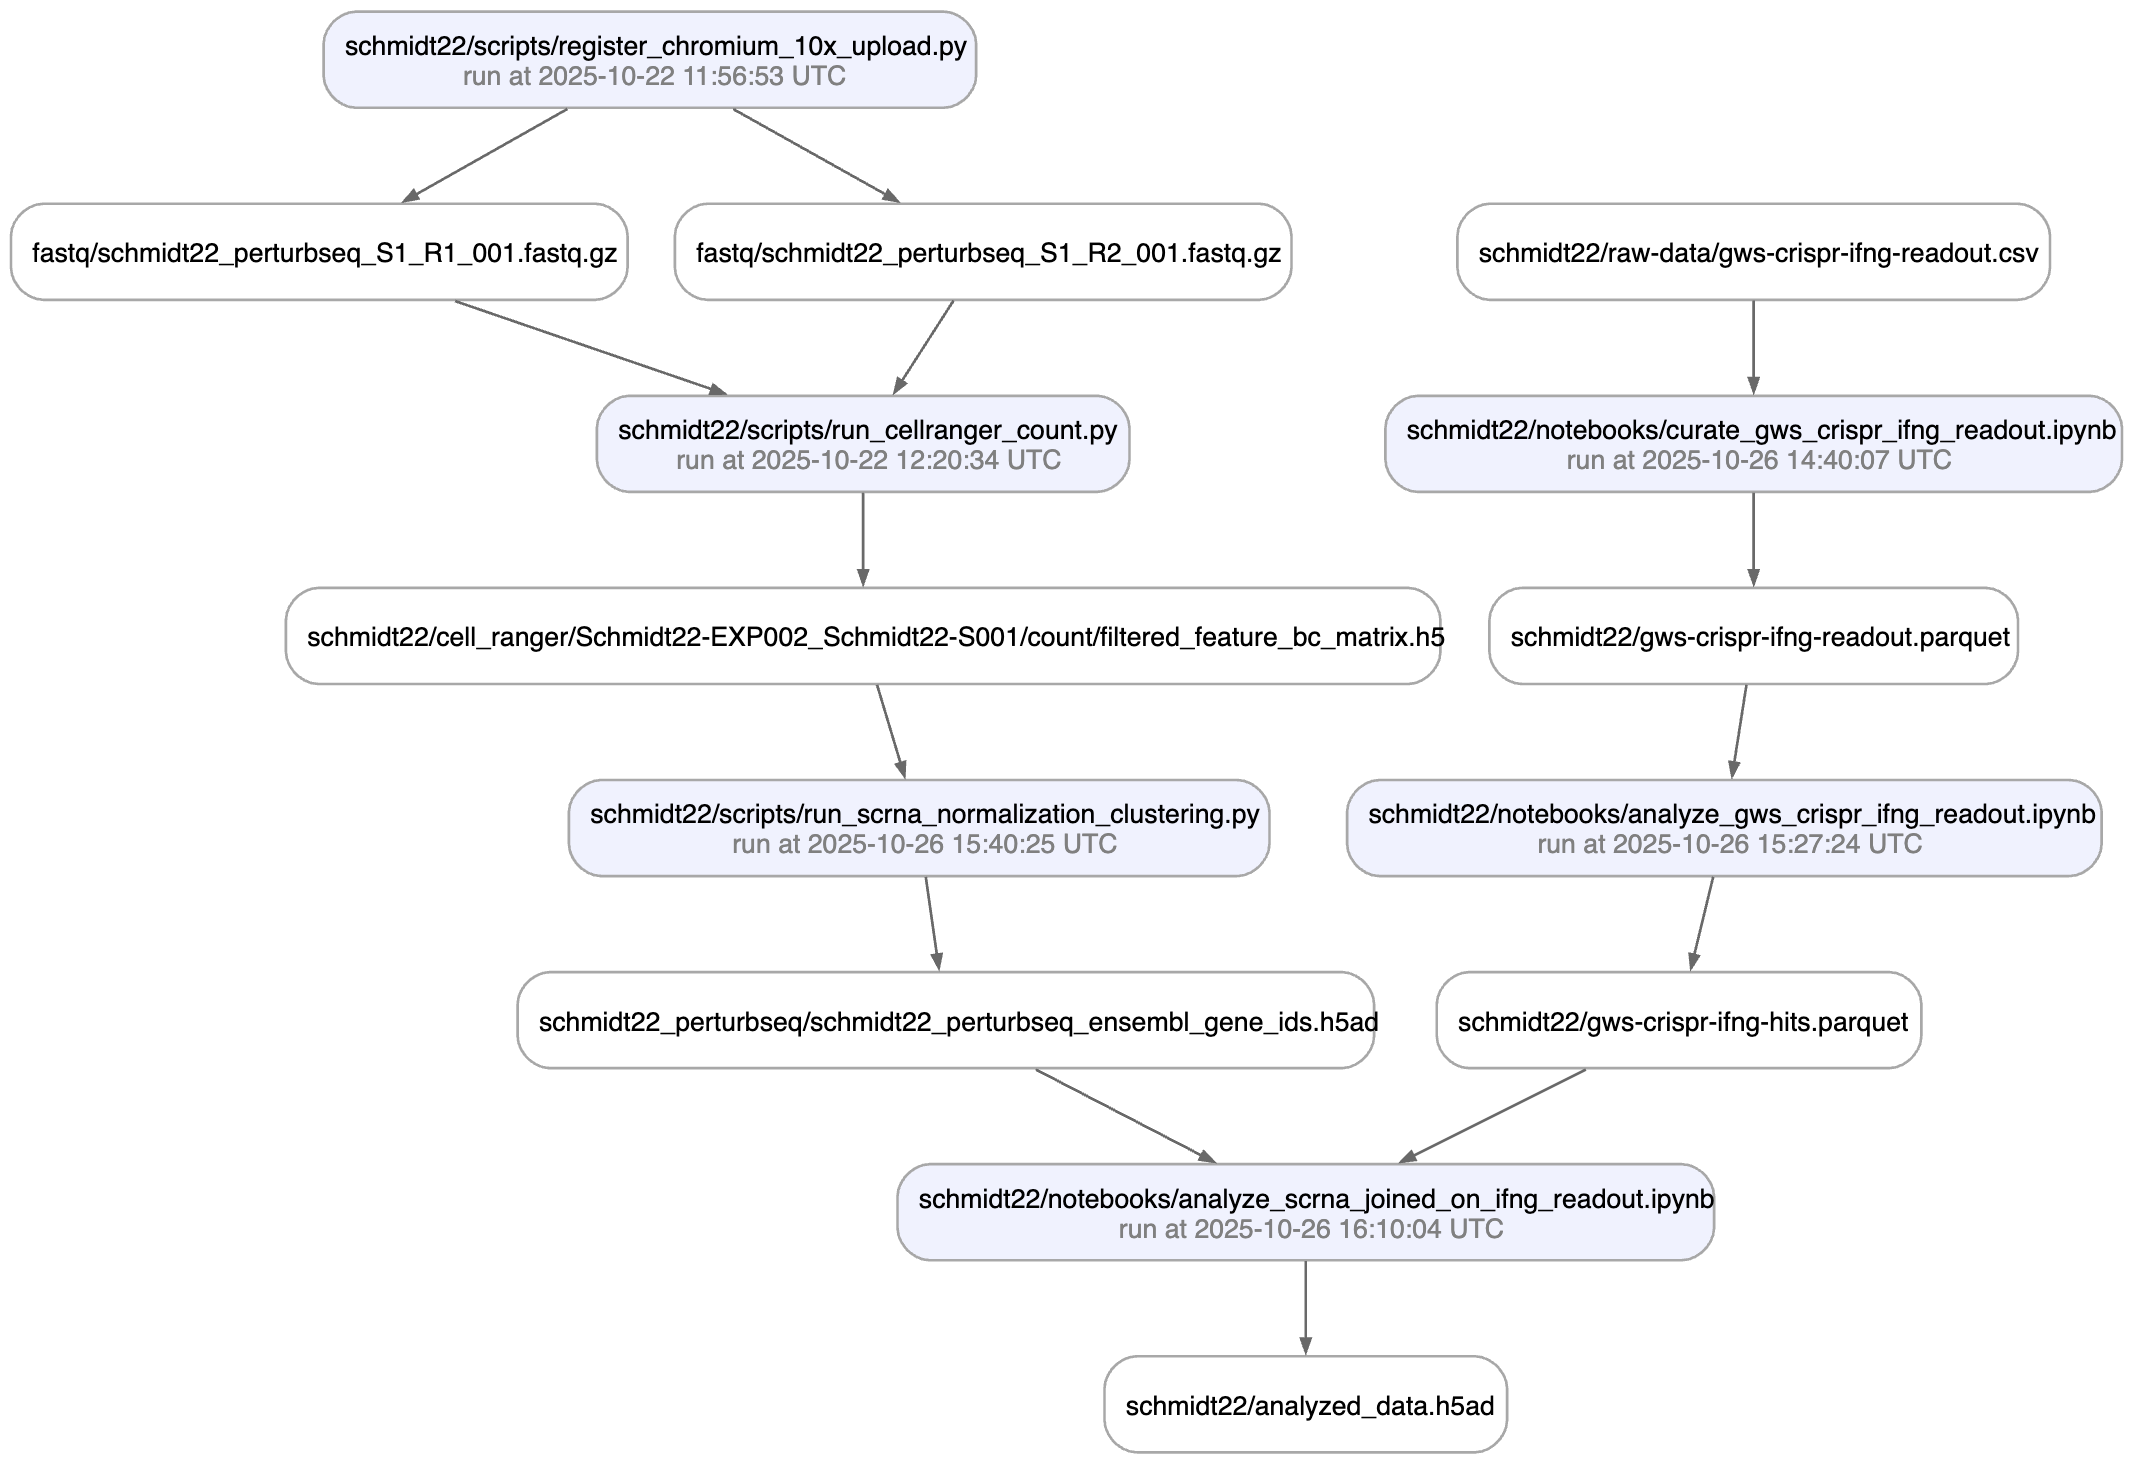
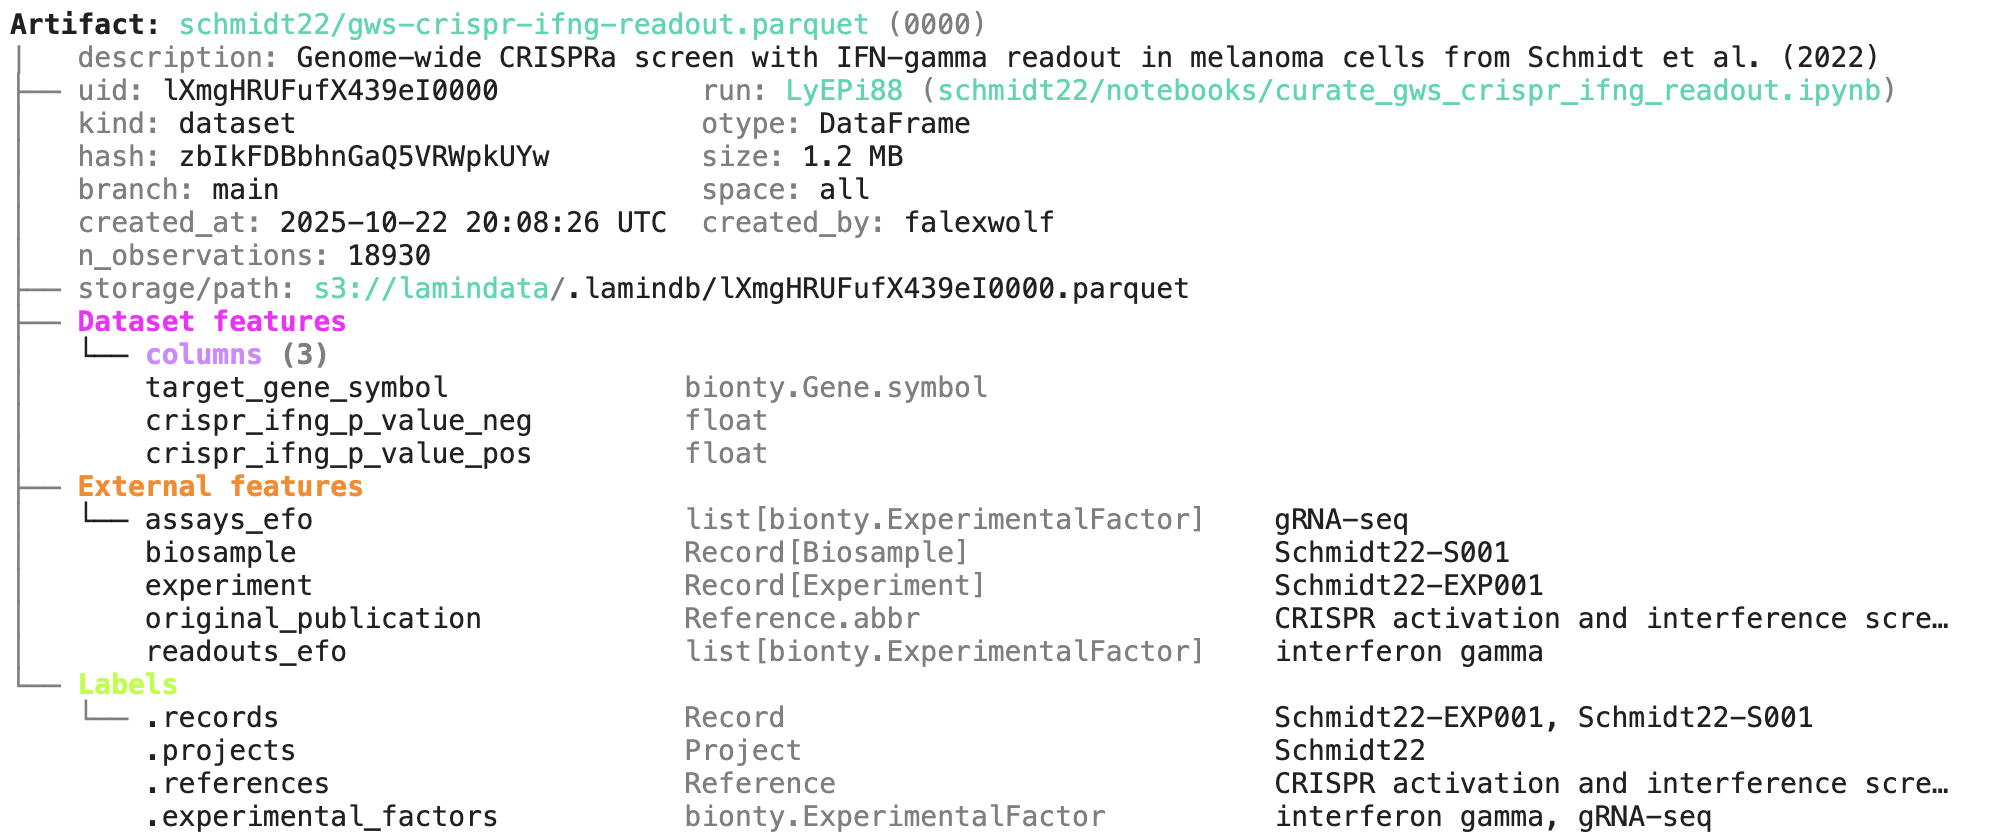
A phenotypic CRISPRa screening result is integrated with scRNA-seq data. Here is the result of the screen input:
Annotate & query artifacts
To annotate and query by labels:
# define labels
my_label = ln.ULabel(name="My universal label").save()
my_project = ln.Project(name="My project label").save()

# annotate
artifact.ulabels.add(my_label)
artifact.projects.add(my_project)

# query
ln.Artifact.filter(ulabels=my_label, projects=my_project).to_dataframe()
# define labels
my_label <- ln$ULabel(name = "My universal label")$save()
my_project <- ln$Project(name = "My project label")$save()

# annotate
artifact$ulabels$add(my_label)
artifact$projects$add(my_project)

# query
ln$Artifact$filter(ulabels = my_label, projects = my_project)$to_dataframe()
To annotate & query by features:
from datetime import date

# define features
gc_content = ln.Feature(name="gc_content", dtype=float).save()
seq_date = ln.Feature(name="seq_date", dtype=date).save()

# annotate
artifact.features.set_values({
    gc_content: 0.55,
    seq_date: date.today(),
})

# query
ln.Artifact.filter(seq_date == date.today()).to_dataframe(include="features")
datetime <- import_module("datetime")
date <- datetime$date

# define features
gc_content <- ln$Feature(name = "gc_content", dtype = "float")$save()
seq_date <- ln$Feature(name = "seq_date", dtype = date)$save()

# annotate
artifact$features$set_values(list(
    gc_content = 0.55,
    seq_date = date$today()
))

# query
ln$Artifact$filter(seq_date == date$today())$to_dataframe(include = "features")
To query by auto-tracked metadata:
# by storage location and size
ln.Artifact.filter(storage__root=ln.settings.storage.root)
ln.Artifact.filter(size__gt=1e6).to_dataframe()

# by data lineage
ln.Artifact.filter(run=run).to_dataframe()
ln.Artifact.filter(run__transform=transform).to_dataframe()

# include more information in resulting dataframe
ln.Artifact.to_dataframe(include=["run__transform__key", "storage__root"])
# by storage location and size
ln$Artifact$filter(storage__root = ln$settings$storage$root)
ln$Artifact$filter(size__gt = 1e6)$to_dataframe()

# by data lineage
ln$Artifact$filter(run = run)$to_dataframe()
ln$Artifact$filter(run__transform = transform)$to_dataframe()

# include more information in resulting dataframe
ln$Artifact$to_dataframe(include = list("run__transform__key", "storage__root"))
Read more: docs.lamin.ai/organize or docs.lamin.ai/query-search
Create records & notes
You can create record types to model metadata for any entity:
# create record types
experiment_type = ln.Record(name="Experiments", is_type=True).save()
sample_type = ln.Record(name="Samples", is_type=True).save()

# create an experiment
experiment1 = ln.Record(
    name="Experiment 1",
    features={seq_date: date.today()},
    type=experiment_type
).save()

# create a sample that links to "Experiment 1" via a feature
experiment = ln.Feature(name="experiment", dtype=experiment_type).save()
sample1 = ln.Record(
    features={gc_content: 0.5, experiment: experiment1},
    type=sample_type
).save()

# export all experiments and all samples
experiment_type.to_dataframe()
sample_type.to_dataframe()
# create record types
experiment_type <- ln$Record(name = "Experiments", is_type = TRUE)$save()
sample_type <- ln$Record(name = "Samples", is_type = TRUE)$save()

# create an experiment
experiment1 <- ln$Record(
    name = "Experiment 1",
    features = list(seq_date = date$today()),
    type = experiment_type
)$save()

# create a sample that links to "Experiment 1" via a feature
experiment <- ln$Feature(name = "experiment", dtype = experiment_type)$save()
sample1 <- ln$Record(
    features = list(gc_content = 0.5, experiment = experiment1),
    type = sample_type
)$save()

# export all experiments and all samples
experiment_type$to_dataframe()
sample_type$to_dataframe()
You can save markdown notes as records:
lamin save <topic>/<my-note.md>
To load a record back as a markdown file, run:
lamin load https://lamin.ai/laminlabs/lamindata/record/mNDJgWFrkWQVW3ox
Watch a mini video: youtu.be/NRzVQXJaRH8
Read more: docs.lamin.ai/manage-records.
Validate datasets
Here is how you ingest a DataFrame:
import pandas as pd

df = pd.DataFrame({
    "seq_str": ["ACGT", "TGCA"],
    "gc_content": [0.55, 0.54],
    "experiment_note": ["Looks great", "Ok"],
    "seq_date": [date(2025, 10, 24), date(2025, 10, 25)],
})
ln.Artifact.from_dataframe(df, key="my_datasets/sequences.parquet").save()  # no validation
pd <- import_module("pandas")

df <- pd$DataFrame(list(
    seq_str = list("ACGT", "TGCA"),
    gc_content = list(0.55, 0.54),
    experiment_note = list("Looks great", "Ok"),
    seq_date = list(date(2025L, 10L, 24L), date(2025L, 10L, 25L))
))
ln$Artifact$from_dataframe(df, key = "my_datasets/sequences.parquet")$save()  # no validation
The simplest way to validate & annotate the content of the dataframe is the built-in schema valid_features:
ln.Feature(name="seq_str", dtype=str).save()  # define remaining features
ln.Feature(name="experiment_note", dtype=str).save()
artifact = ln.Artifact.from_dataframe(
    df,
    key="my_datasets/sequences.parquet",
    schema="valid_features"  # validate columns against features
).save()
artifact.describe()
ln$Feature(name = "seq_str", dtype = "str")$save()  # define remaining features
ln$Feature(name = "experiment_note", dtype = "str")$save()
artifact <- ln$Artifact$from_dataframe(
    df,
    key = "my_datasets/sequences.parquet",
    schema = "valid_features"  # validate columns against features
)$save()
artifact$describe()
You can filter for datasets by schema and then launch distributed queries or batch load distributed datasets. For tables, see: docs.lamin.ai/tables. For arrays, see: docs.lamin.ai/arrays.
Watch a mini video: youtu.be/Ji6E7hTnReQ
To validate an AnnData, call:
import anndata as ad
import numpy as np
import pandas as pd

adata = ad.AnnData(
    X=np.ones((21, 10)),
    obs=pd.DataFrame({'cell_type_by_model': ['T cell', 'B cell', 'NK cell'] * 7}),
    var=pd.DataFrame(index=[f'ENSG{i:011d}' for i in range(10)])
)
artifact = ln.Artifact.from_anndata(
    adata,
    key="my_datasets/scrna.h5ad",
    schema="ensembl_gene_ids_and_valid_features_in_obs"
).save()
artifact.describe()
ad <- import_module("anndata")
np <- import_module("numpy")
pd <- import_module("pandas")

adata <- anndata::AnnData(
    X = np$ones((21, 10)),
    obs = pd$DataFrame(list(cell_type_by_model = rep(list('T cell', 'B cell', 'NK cell'), 7))),
    var = pd$DataFrame(index = sprintf("ENSG%010d", 1:10))
)
artifact <- ln$Artifact$from_anndata(
    adata,
    key = "my_datasets/scrna.h5ad",
    schema = "ensembl_gene_ids_and_valid_features_in_obs"
)$save()
artifact$describe()
To validate a SpatialData or any other array-like dataset, you need to construct a Schema. You can do this by composing simple pandera-style schemas: docs.lamin.ai/curate.
Use branching & versioning
LaminDB co-versions code and datasets for you.
If you edit and run the create_fasta.py script, you’ll automatically create a new version of the transform and the sample.fasta artifact.
The edited script
# create_fasta.py
import lamindb as ln

ln.track()
open("sample.fasta", "w").write(">seq1\nTGCA\n")  # a new sequence
ln.Artifact("sample.fasta", key="sample.fasta", features={"experiment": "Experiment 1"}).save()  # annotate with the new experiment
ln.finish()
# create_fasta$py
library(laminr)
ln <- import_module("lamindb")

ln$track()
writeLines(">seq1\nTGCA\n", "sample.fasta")  # a new sequence
ln$Artifact("sample.fasta", key = "sample.fasta", features = list(experiment = "Experiment 1"))$save()  # annotate with the new experiment
ln$finish()
artifact_latest = ln.Artifact.get(key="sample.fasta")  # pass version for a previous version: ln.Artifact.get(key="sample.fasta", version="1.0")
artifact_latest.versions.to_dataframe()                # all versions of that artifact
artifact_latest.run.transform.versions.to_dataframe()  # all versions of the transform that created the artifact
artifact_latest <- ln$Artifact$get(key = "sample.fasta")  # pass version for a previous version: ln$Artifact$get(key = "sample.fasta", version = "1.0")
artifact_latest$versions$to_dataframe()                # all versions of that artifact
artifact_latest$run$transform$versions$to_dataframe()  # all versions of the transform that created the artifact
To isolate changes, create a contribution branch and switch to it as in git:
lamin switch -c my_branch
To merge a contribution branch into main, run:
lamin switch main  # switch to the main branch
lamin merge my_branch  # merge contribution branch into main
Read more: docs.lamin.ai/manage-changes.
Watch a mini video: youtu.be/rzRwcMj6-fc
Manage ontologies
Plugin bionty gives you >20 public ontologies as SQLRecord registries. This was used to validate the ENSG ids in the adata just before.
import bionty as bt

bt.CellType.import_source()  # import the default ontology
bt.CellType.to_dataframe()   # your extensible cell type ontology in a simple registry
bt <- import_module("bionty")

bt$CellType$import_source()  # import the default ontology
bt$CellType$to_dataframe()   # your extensible cell type ontology in a simple registry
You can then create objects, e.g. for labeling, analogous to ULabel, Project, or Record:
t_cell = bt.CellType.get(name="T cell")
artifact.cell_types.add(t_cell)
t_cell <- bt$CellType$get(name = "T cell")
artifact$cell_types$add(t_cell)
Read more: docs.lamin.ai/manage-ontologies.
Watch a mini video: youtu.be/3vpWjHj3Kw8