Append a new dataset 
 
We have one dataset in storage and are about to receive a new dataset.
In this notebook, we’ll see how to manage the situation.
import lamindb as ln
import bionty as bt
import readfcs

bt.settings.organism = "human"

ln.track("SmQmhrhigFPL0000")
Show code cell output
→ connected lamindb: testuser1/test-facs
→ created Transform('SmQmhrhigFPL0000', key='facs2.ipynb'), started new Run('IWBejVriqKXnAw8e') at 2026-10-28 10:01:32 UTC
Ingest a new artifact
Access  
Let us validate and register another .fcs file from Oetjen18:
filepath = readfcs.datasets.Oetjen18_t1()

adata = readfcs.read(filepath)
# since anndata>=0.12.0, `/` is not allowed in keys
adata.var.index = adata.var.index.str.replace("/", "|")
adata.var["marker"] = adata.var["marker"].str.replace("/", "|")
adata.uns["meta"]["spill"].index = adata.uns["meta"]["spill"].index.str.replace(
    "/", "|"
)
adata.uns["meta"]["spill"].columns = adata.uns["meta"]["spill"].columns.str.replace(
    "/", "|"
)
adata
Show code cell output
/opt/hostedtoolcache/Python/3.12.15/x64/lib/python3.12/functools.py:912: ImplicitModificationWarning: Transforming to str index.
  return dispatch(args[0].__class__)(*args, **kw)
AnnData object with n_obs × n_vars = 241552 × 20
    var: 'n', 'channel', 'marker', 'PnR', 'PnB', 'PnE', 'PnV', 'PnG'
    uns: 'meta'
Transform: normalize  
import pytometry as pm
pm.pp.split_signal(adata, var_key="channel")
Show code cell output
/opt/hostedtoolcache/Python/3.12.15/x64/lib/python3.12/site-packages/pytometry/pp/_process_data.py:230: FutureWarning: The method var_keys is deprecated and will be removed in the future. Use var instead of var_keys. (e.g. `k in adata.var` or `str(adata.var.columns.tolist())`)
  if key_in not in adata.var_keys():
/opt/hostedtoolcache/Python/3.12.15/x64/lib/python3.12/site-packages/pytometry/pp/_process_data.py:66: FutureWarning: The method var_keys is deprecated and will be removed in the future. Use var instead of var_keys. (e.g. `k in adata.var` or `str(adata.var.columns.tolist())`)
  elif var_key in adata.var_keys():
pm.pp.compensate(adata)
pm.tl.normalize_biExp(adata)
adata = adata[  # subset to rows that do not have nan values
    adata.to_df().isna().sum(axis=1) == 0
]
adata.to_df().describe()
Show code cell output
| CD95 | CD8 | CD27 | CXCR4 | CCR7 | LIVE|DEAD | CD4 | CD45RA | CD3 | CD49B | CD14|19 | CD69 | CD103 | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| count | 241552.000000 | 241552.000000 | 241552.000000 | 241552.000000 | 241552.000000 | 241552.000000 | 241552.000000 | 241552.000000 | 241552.000000 | 241552.000000 | 241552.000000 | 241552.000000 | 241552.000000 |
| mean | 1049.015217 | 1293.326611 | 1240.562589 | 1163.779802 | 795.800526 | 1897.421272 | 1671.292539 | 692.529545 | 820.430567 | 870.801405 | 1429.846115 | 608.127554 | 963.554032 |
| std | 634.579243 | 831.914759 | 675.886939 | 559.254219 | 579.415556 | 922.604717 | 832.483038 | 853.018613 | 680.059269 | 587.595901 | 565.002417 | 653.581155 | 649.819303 |
| min | 0.000000 | 0.000000 | 0.000000 | 0.000000 | 0.000000 | 0.000000 | 0.000000 | 0.000000 | 0.000000 | 0.000000 | 20.200048 | 0.000000 | 0.000000 |
| 25% | 528.414959 | 485.497959 | 613.954166 | 693.165730 | 398.802203 | 1100.959173 | 900.084668 | 0.000000 | 404.329481 | 418.861659 | 1014.659374 | 0.000000 | 451.780983 |
| 50% | 989.333555 | 1188.070828 | 1154.625279 | 1081.005669 | 592.531495 | 1960.735775 | 1702.230733 | 383.136112 | 558.805440 | 784.715150 | 1355.348975 | 434.837372 | 688.743994 |
| 75% | 1541.398578 | 2033.498971 | 1743.629192 | 1540.015342 | 1149.777722 | 2628.235834 | 2328.352403 | 721.017068 | 1003.313507 | 1370.356836 | 1793.131327 | 1096.707626 | 1386.160643 |
| max | 4054.890968 | 4064.772534 | 4096.000000 | 4042.557502 | 3991.302815 | 4096.000000 | 4096.000000 | 3958.503398 | 3933.310314 | 4075.465630 | 4096.000000 | 4003.981981 | 4021.460156 |
Validate cell markers  
Let’s see how many markers validate:
validated = bt.CellMarker.validate(adata.var.index)
Show code cell output
! 9 unique terms (69.20%) are not validated for name: 'CD95', 'CXCR4', 'CCR7', 'LIVE|DEAD', 'CD4', 'CD49B', 'CD14|19', 'CD69', 'CD103'
Let’s standardize and re-validate:
adata.var.index = bt.CellMarker.standardize(adata.var.index)
validated = bt.CellMarker.validate(adata.var.index)
Show code cell output
! 7 unique terms (53.80%) are not validated for name: 'CD95', 'CXCR4', 'LIVE|DEAD', 'CD49B', 'CD14|19', 'CD69', 'CD103'
/tmp/ipykernel_3831/92294437.py:1: ImplicitModificationWarning: Trying to modify index of attribute `.var` of view, initializing view as actual.
  adata.var.index = bt.CellMarker.standardize(adata.var.index)
Next, register non-validated markers from Bionty:
records = bt.CellMarker.from_values(adata.var.index[~validated])
ln.save(records)
Manually create 1 marker:
bt.CellMarker(name="CD14|19").save()
Show code cell output
CellMarker(uid='67ZpJGSKNFyEAq', abbr=None, synonyms=None, description=None, name='CD14|19', gene_symbol=None, ncbi_gene_id=None, uniprotkb_id=None, branch_id=1, created_on_id=1, space_id=1, created_by_id=1, run_id=2, source_id=None, organism_id=1, created_at=2026-10-28 10:01:36 UTC, is_locked=False)
Move metadata to obs:
validated = bt.CellMarker.validate(adata.var.index)
adata.obs = adata[:, ~validated].to_df()
adata = adata[:, validated].copy()
Show code cell output
! 1 unique term (7.70%) is not validated for name: 'LIVE|DEAD'
Now all markers pass validation:
validated = bt.CellMarker.validate(adata.var.index)
assert all(validated)
Register  
schema = ln.Schema.get(name="FACS-AnnData-schema")
curator = ln.curators.AnnDataCurator(adata, schema=schema)
artifact = curator.save_artifact(description="Oetjen18_t1")
Show code cell output
! no values were validated for columns!
→ returning schema with same hash: Schema(uid='0000000000000000', is_type=False, name='FACS-sample-metadata', description=None, n_members=None, coerce=None, flexible=True, itype='Feature', otype=None, suffix=None, hash='kMi7B_N88uu-YnbTLDU-DA', minimal_set=True, ordered_set=False, maximal_set=False, branch_id=1, created_on_id=1, space_id=1, created_by_id=1, run_id=1, type_id=None, created_at=2026-10-28 10:01:26 UTC, is_locked=False)
Annotate with more labels:
efs = bt.ExperimentalFactor.lookup()
organism = bt.Organism.lookup()

artifact.experimental_factors.add(efs.fluorescence_activated_cell_sorting)
artifact.organisms.add(organism.human)
artifact.describe()
Show code cell output
Artifact:  (0000)
|   description: Oetjen18_t1
├── uid: DnHcIgG0FYtkOxUc0000            run: IWBejVr (facs2.ipynb)
│   kind: dataset                        otype: AnnData
│   hash: d6l9MySX8FVezzyFggkKvQ         size: 44.4 MB
│   branch: main                         space: all
│   created_at: 2026-10-28 10:01:36 UTC  created_by: testuser1
│   n_observations: 241552               schema: FACS-AnnData-schema
├── storage/path: /home/runner/work/lamin-usecases/lamin-usecases/docs/test-facs/.lamindb/DnHcIgG0FYtkOxUc0000.h5ad
├── Dataset features
│   ├── obs (None)
│   └── var.T (12 bionty.CellMarker)
│       CD103                          num
│       CD14|19                        num
│       CD27                           num
│       CD3                            num
│       CD45RA                         num
│       CD49B                          num
│       CD69                           num
│       CD8                            num
│       CD95                           num
│       CXCR4                          num
│       Ccr7                           num
│       Cd4                            num
└── Entities
    └── .organisms                     bionty.Organism                      human
        .experimental_factors          bionty.ExperimentalFactor            fluorescence-activated cell sorting
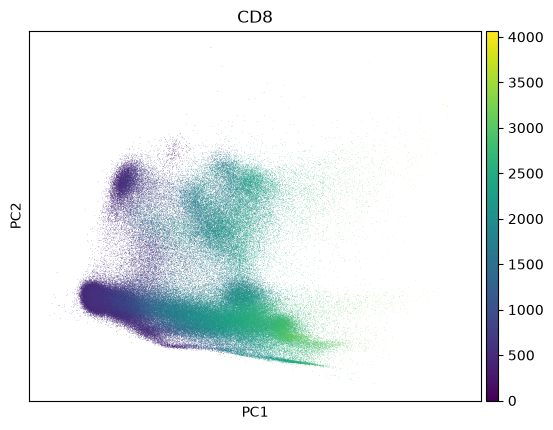
Inspect a PCA fo QC - this collection looks much like noise:
import scanpy as sc

markers = bt.CellMarker.lookup()

sc.pp.pca(adata)
sc.pl.pca(adata, color=markers.cd8.name)
Show code cell output
Create a new version of the collection by appending a artifact
Query the old version:
collection_v1 = ln.Collection.get(key="My versioned cytometry collection")
collection_v2 = ln.Collection(
    [artifact, collection_v1.ordered_artifacts[0]],
    revises=collection_v1,
    version="2",
)
collection_v2.describe()
Show code cell output
Collection: My versioned cytometry collection (2)
└── uid: Me2xfi0bHcN93XE50001                                                            run: IWBejVr (facs2.ipynb)
    branch: main                                                                         space: all
    created_at: <django.db.models.expressions.DatabaseDefault object at 0x7f718d63ad20>  created_by: testuser1
collection_v2.save()
Show code cell output
Collection(uid='Me2xfi0bHcN93XE50001', key='My versioned cytometry collection', description=None, hash='SaHaV6QKcWEz6PLFYLjK2Q', reference=None, reference_type=None, meta_artifact=None, branch_id=1, created_on_id=1, space_id=1, created_by_id=1, run_id=2, schema_id=None, created_at=2026-10-28 10:01:38 UTC, is_locked=False, version_tag='2', is_latest=True)