Transfer & sync across databases 
 
This guide shows how to sync objects from a source database to your default database.
If you don’t have a database, create one with the modules you need on the target.
Here we pass bionty because we’ll transfer biological entities:
lamin init --modules bionty
Show code cell output
→ initialized database anonymous/docs in /home/runner/work/lamindb/lamindb/docs
Using sync
You can sync an object from any database to your current database:
lamin io sync https://lamin.ai/laminlabs/lamindata/record/gL3TbX2qZQmCwTAU
import lamindb as ln

ln.core.sync(
    registry=ln.Record,
    uid="gL3TbX2qZQmCwTAU",
    source_db="laminlabs/lamindata",
)
To sync annotations in addition to the bare object, pass the --transfer / transfer argument:
"sqlrecord": the object and its foreign keys"notes": its associated notes"annotations": its annotations
You can also pass a --depth argument for HasType objects, which indicates how deeply you want to recurse through the type hierarchy. For details, see sync().
space, branch, and created_on are handled differently from every other foreign key. Other foreign keys, such as created_by, storage, schema, and type, are copied, and a missing row is created on the target.
Space. Mapped by uid. When that space is not attached to the target database, sync raises. Attach the space, then sync again. Sync does not create a space.
Branch and
created_on. Each is mapped by uid when that branch already exists on the target.main,archive, andtrashalways do. When a uid is absent, that field is set to the current branch of the transfer. Sync does not create a branch.
What the high-level sync command does is wrapping the lower-level SQLRecord.save() API. Let’s walk through it!
Using save
Query the object on the source, then call .save():
import lamindb as ln

# optionally track the run
ln.track()
# instantiate a database object for your source database
db = ln.DB("laminlabs/lamindata")
# query the artifact on the source database
artifact = db.Artifact.get(key="example_datasets/mini_immuno/dataset1.h5ad")
# sync the artifact to the current database
artifact.save()
Show code cell output
→ connected lamindb: anonymous/docs
→ created Transform('X7wtN6z0OA3G0000', key='transfer.ipynb'), started new Run('7hL5VVUaPpVBKDE0') at 2026-10-19 14:41:58 UTC
• tip: to identify the notebook across renames, pass the uid: ln.track("X7wtN6z0OA3G")
• tip: to work with the additional module (pertdb) of database laminlabs/lamindata, configure your environment for it: lamin settings modules set bionty,pertdb
→ Artifact example_datasets/mini_immuno/dataset1.h5ad: 5 transferred, 0 already on target
Artifact(uid='9K1dteZ6Qx0EXK8g0000', key='example_datasets/mini_immuno/dataset1.h5ad', description='Flow cytometry readouts on invitro cell culture', suffix='.h5ad', kind='dataset', otype='AnnData', size=31672.0, hash='FB3CeMjmg1ivN6HDy6wsSg', n_files=None, n_observations=3.0, extra_data=None, branch_id=1, created_on_id=1, space_id=1, storage_id=2, run_id=2, schema_id=1, created_by_id=3, created_at=2025-07-29 12:27:25 UTC, is_locked=False, version_tag=None, is_latest=True)
To transfer annotations, pass transfer="annotations":
# query again so that `artifact` points to the object on the source database
artifact = db.Artifact.get(key="example_datasets/mini_immuno/dataset1.h5ad")
# sync with annotations
artifact.save(transfer="annotations")
Show code cell output
→ Artifact example_datasets/mini_immuno/dataset1.h5ad: 20 transferred, 6 already on target
Artifact(uid='9K1dteZ6Qx0EXK8g0000', key='example_datasets/mini_immuno/dataset1.h5ad', description='Flow cytometry readouts on invitro cell culture', suffix='.h5ad', kind='dataset', otype='AnnData', size=31672, hash='FB3CeMjmg1ivN6HDy6wsSg', n_files=None, n_observations=3, extra_data=None, branch_id=1, created_on_id=1, space_id=1, storage_id=2, run_id=2, schema_id=1, created_by_id=3, created_at=2025-07-29 12:27:25 UTC, is_locked=False, version_tag=None, is_latest=True)
The artifact now has all feature & label annotations:
artifact.describe()
Show code cell output
Artifact: example_datasets/mini_immuno/dataset1.h5ad (0000)
|   description: Flow cytometry readouts on invitro cell culture
├── uid: 9K1dteZ6Qx0EXK8g0000            run: ovWklUW (__lamindb_transfer__/4XIuR0tvaiXM)
│   kind: dataset                        otype: AnnData
│   hash: FB3CeMjmg1ivN6HDy6wsSg         size: 30.9 KB
│   branch: main                         space: all
│   created_at: 2025-07-29 12:27:25 UTC  created_by: falexwolf
│   n_observations: 3                    schema: anndata_ensembl_gene_ids_and_valid_features_in_obs
├── storage/path: s3://lamindata/.lamindb/9K1dteZ6Qx0EXK8g0000.h5ad
├── Dataset features
│   ├── obs (8)
│   │   assay_oid                      bionty.ExperimentalFactor.ontology…  EFO:0008913
│   │   cell_type_by_expert            bionty.CellType                      CD8-positive, alpha-beta T cell
│   │   cell_type_by_model             bionty.CellType                      B cell, T cell
│   │   concentration                  str
│   │   donor                          str
│   │   perturbation                   ULabel                               DMSO, IFNG
│   │   sample_note                    str
│   │   treatment_time_h               num
│   └── var.T (3 bionty.Gene)
│       CD14                           num
│       CD4                            num
│       CD8A                           num
└── Entities
    └── .ulabels                       ULabel                               DMSO, IFNG
        .projects                      Project                              Tutorials
        .cell_types                    bionty.CellType                      B cell, T cell, CD8-positive, alpha-be…
        .experimental_factors          bionty.ExperimentalFactor            single-cell RNA sequencing
The sync is zero-copy: the data itself remains in the original storage location.
artifact.path
Show code cell output
S3QueryPath('lamindata/.lamindb/9K1dteZ6Qx0EXK8g0000.h5ad', protocol='s3')
Data lineage indicates the source database of the sync:
artifact.view_lineage()
Show code cell output
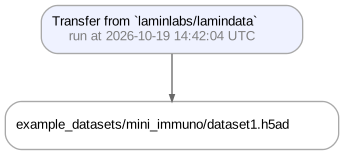
The run that initiated the transfer is linked via initiated_by_run:
artifact.run.initiated_by_run.transform
Show code cell output
Transform(uid='X7wtN6z0OA3G0000', key='transfer.ipynb', description='Transfer & sync across databases [](https://github.com/laminlabs/lamindb/blob/main/docs/transfer.md)', kind='notebook', hash=None, reference=None, reference_type=None, environment=None, plan=None, branch_id=1, created_on_id=1, space_id=1, run_id=None, created_by_id=1, created_at=2026-10-19 14:41:58 UTC, is_locked=False, version_tag=None, is_latest=True)
Upon calling .save() again, lamindb identifies that the object already exists in the target database and simply maps it:
artifact = db.Artifact.get(key="example_datasets/mini_immuno/dataset1.h5ad")
artifact.save()
Show code cell output
→ Artifact example_datasets/mini_immuno/dataset1.h5ad: 0 transferred, 1 already on target
Artifact(uid='9K1dteZ6Qx0EXK8g0000', key='example_datasets/mini_immuno/dataset1.h5ad', description='Flow cytometry readouts on invitro cell culture', suffix='.h5ad', kind='dataset', otype='AnnData', size=31672, hash='FB3CeMjmg1ivN6HDy6wsSg', n_files=None, n_observations=3, extra_data=None, branch_id=1, created_on_id=1, space_id=1, storage_id=2, run_id=2, schema_id=1, created_by_id=3, created_at=2025-07-29 12:27:25 UTC, is_locked=False, version_tag=None, is_latest=True)
A data record can be synced only after its type is already in the target database. EXP-RNA-032 belongs to the RNA-seq record frame, so transfer that frame first:
rna_seq_frame = db.Record.get("gL3TbX2qZQmCwTAU")
rna_seq_frame.save(transfer="annotations")
Show code cell output
→ Record RNA-seq: 53 transferred, 12 already on target
Record(uid='gL3TbX2qZQmCwTAU', is_type=True, name='RNA-seq', description='Bulk RNA-seq experiments.', reference=None, reference_type=None, extra_data=None, branch_id=1, created_on_id=1, space_id=1, created_by_id=2, type_id=1, schema_id=4, run_id=2, created_at=2026-05-04 13:44:23 UTC, is_locked=False)
Now transfer the experiment record:
record = db.Record.get("mNDJgWFrkWQVW3ox")
record.save(transfer="annotations")
record.describe()
Show code cell output
→ Record EXP-RNA-032: 15 transferred, 57 already on target
Record: EXP-RNA-032
├── uid: mNDJgWFrkWQVW3ox                run: ovWklUW (__lamindb_transfer__/4XIuR0tvaiXM)
│   type: RNA-seq                        is_type: False
│   schema:                              reference:
│   branch: main                         space: all
│   created_at: 2026-08-20 13:38:38 UTC  created_by: sunnyosun
├── Features
│   └── assay                          bionty.ExperimentalFactor            RNA-Seq
│       biosamples                     Record[H1jrr6bRnfckiB7Q, is_type='…  EXP-RNA-032 HepG2 Compound A RNA-seq
│       cell_line                      bionty.CellLine                      Hep G2 cell
│       disease                        bionty.Disease                       hepatocellular carcinoma
│       instrument                     bionty.ExperimentalFactor            Illumina NovaSeq 6000
│       library_preparation            bionty.ExperimentalFactor            NEBNext Ultra II RNA Library Prep
│       organism                       bionty.Organism                      human
│       owner                          User                                 Koncopd
│       project                        Project                              Record demo
│       qc_status                      ULabel[QCStatus]                     unknown
│       techsamples                    Record[bf6ITReCW0wLEloj, is_type='…  EXP-RNA-032 HepG2 Compound A FASTQs
│       tissue                         bionty.Tissue                        liver
│       treatment                      Record[Perturbations]                Compound A
│       date_of_experiment             date                                 2026-08-18
│       description                    str                                  Hep G2 Compound A dose series (0 / 1 /…
│       n_samples                      int                                  3
│       notes                          str                                  Liver metabolic response; FASTQ QC sti…
└── Notes:
    │ ### Experiment Overview & Objective
    │
    │ Investigate the acute transcriptional response and potential liver metabolic pat …
    │
    │ ### Experimental Design
    │
    │ * **Model System:** HepG2 cells (Human Hepatocellular Carcinoma / Liver Tissue)
    │ * **Treatment Parameters:**
    │ * **Compound:** Compound A
    │ * **Dose Points:** 3 conditions (0 µM vehicle control, 1 µM low dose, 10 µM high …
    │ * **Timepoint:** 12-hour incubation
    │ * **Sample Count:** $n = 3$ total samples
    │
    │ ### Protocol & Sequencing Specifications
    │
    │ * **Library Preparation:** NEBNext Ultra II RNA Library Prep
    │ * **Sequencing Platform:** Illumina NovaSeq 6000
    │ * **Assay Type:** Bulk RNA-Seq
    │ * **Bioinformatics Pipeline Target:** `nf-core/rnaseq` workflow
    │
    │ ### Data Status & Immediate Next Steps
    │
    │ 1. **FASTQ Quality Control:** Pending initial raw read QC assessment (FastQC / M …
    │ 2. **Alignment & Quantification:** Align reads to human reference genome (GRCh38 …
    │ 3. **Downstream Target Analysis:**
    │ * Differential gene expression (DGE) analysis between treated vs. control sample …
    │ * Pathway enrichment analysis targeting hepatic drug metabolism, cytochrome P450 …
How do I know if an object is in the default database or elsewhere?
Every SQLRecord object has an attribute ._state.db which can take the following values:
None: the object has not yet been saved to any database"default": the object is saved on the default database instance"account/name": the object is saved on a non-default database instance referenced byaccount/name(e.g.,laminlabs/lamindata)
Show code cell content
assert artifact.run.transform.description == "Transfer from `laminlabs/lamindata`"
assert artifact.run.transform.key == "__lamindb_transfer__/4XIuR0tvaiXM"
assert artifact.run.transform.uid == "4XIuR0tvaiXM0000"
assert artifact.run.initiated_by_run.transform.description.startswith("Transfer & sync")
assert artifact.features.slots
for schema in artifact.features.slots.values():
    _ = schema.index

rna_seq = ln.Record.get("gL3TbX2qZQmCwTAU")
assert rna_seq.is_type
assert rna_seq._state.db == "default"

source = db.Record.get("mNDJgWFrkWQVW3ox")
expected = source.features.get_values()
got = record.features.get_values()
assert record._state.db == "default"
assert set(got) == set(expected)
for key in (
    "date_of_experiment",
    "organism",
    "assay",
    "project",
    "n_samples",
    "notes",
    "name",
    "description",
    "owner",
):
    assert got[key] == expected[key]

again = db.Record.get("mNDJgWFrkWQVW3ox").save(transfer="annotations")
assert again.id == record.id
→ Record EXP-RNA-032: 0 transferred, 68 already on target